Case study · Designing for AI · Microsoft
Bulk drive classification, powered by machine learning.
Machine-learning recommendations that turned classifying drives one at a time into a single reviewable list, and lifted the metric MileIQ runs on.
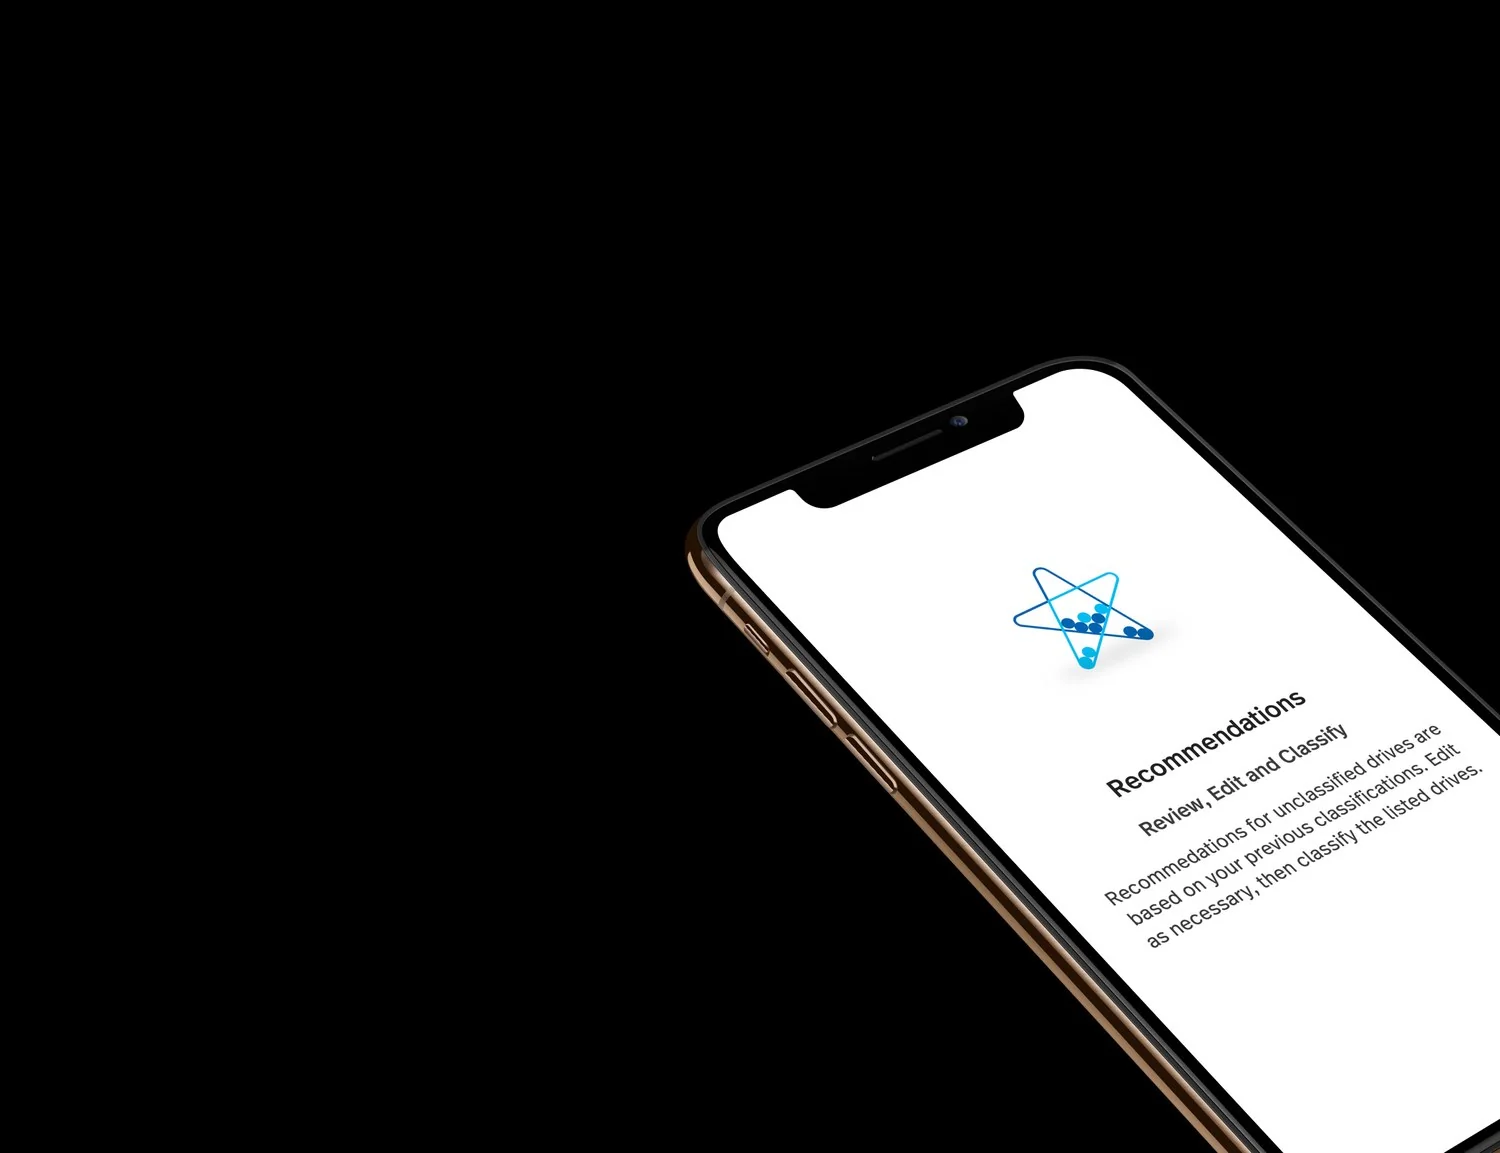
I led design end to end for a feature that uses machine learning to recommend how users classify their drives. It lifted MileIQ's core engagement metric, the share of logged drives that get classified, by 10–20 percentage points.
Microsoft filed a patent on the ML model behind the feature. As the only designer on the team, I owned the work from problem framing through final visual design.
The problem
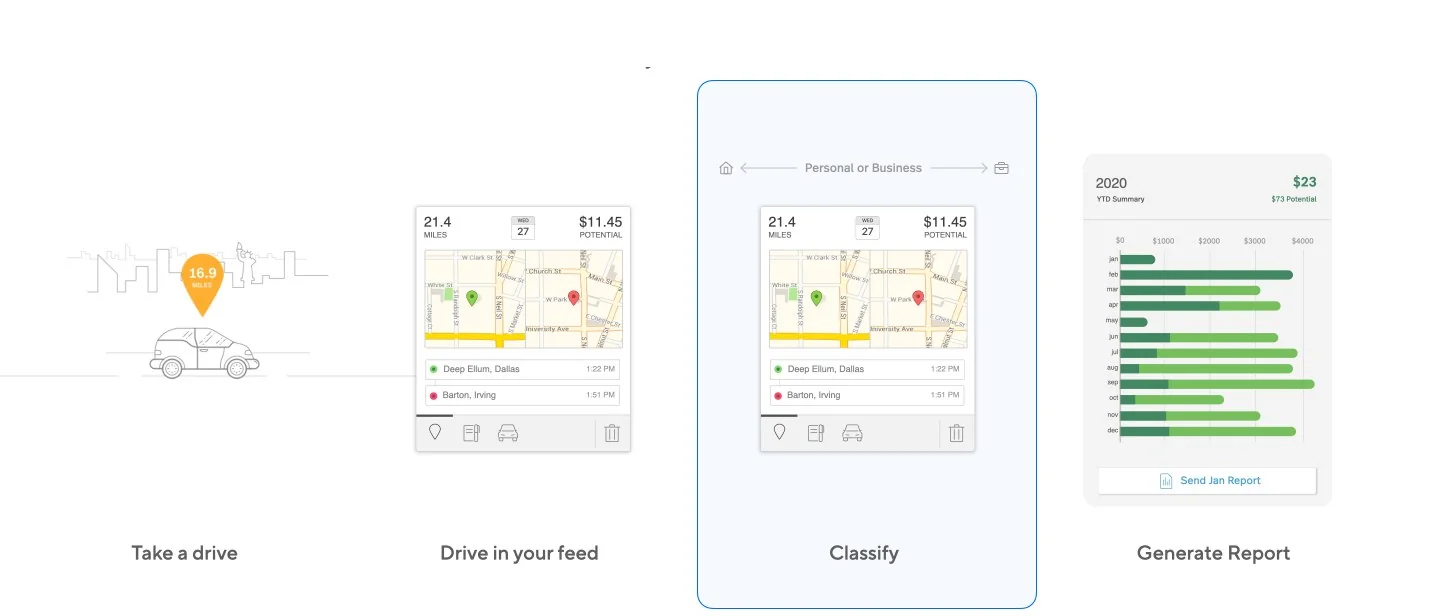
Classifying drives is the one thing MileIQ exists to do.
Every drive the app logs has to be marked Business or Personal, because that's what becomes a tax deduction, and it was the one task users kept falling behind on.
Across user interviews, surveys, feedback, and CX tickets, classification issues were the single biggest problem by volume. Two causes dominated.
Too manual. There were too many drives to classify one at a time.
Accuracy anxiety. Without classifying right away, users couldn't recall a drive's context later, so they guessed or skipped it.
For the user, an unclassified drive is a missed deduction, up to $6,200/year on a $59.99/year subscription. For the business, classification is the product's value, and users who stop classifying churn.
- Daily drives: 8–10 · 79% Business / 16% Personal / 5% unclassified
- Archetype: construction workers, realtors, freelancers
- Classifies: weekly, monthly, or once a year
Make classification less manual, more efficient, and more accurate, at the same time.
My role
Sole designer,
end to end.
I was the sole product designer, working over six weeks with one PM, one UX writer, one data scientist, and four engineers. I owned design from problem framing through final visual work, and led the design reviews that kept the team aligned on each decision.
- Practices: problem framing, design strategy, user research, design reviews
- Deliverables: user flows, interaction design, wireframes, prototype, visual design
- Team: 1 PM, 1 UX writer, 1 data scientist, 4 engineers
Because I was the only designer, every design decision in this case study was mine, so there's no team attribution to untangle.
Key decisions
Three calls that shaped the feature.
ML recommendations, not more automation
MileIQ already had automation, rules that classified repeated drives (a daily commute, say) the same way each time. It wasn't moving the rate enough, because rules only catch predictable patterns, and most driving isn't predictable. Instead of adding rules, I reframed the problem from "automate more" to "make the app intelligent," using the user's own classification history to recommend classifications for everything else, applied in bulk.
A recommendation can be wrong in a way a deterministic rule can't. That made trust the central design problem of the project.
A list, not buckets, cards, or tabs
I explored several ways to present recommendations (grouped buckets, a session summary, tabs, and a plain list) and tested them with users. Buckets and cards looked cleaner but hid the individual drives behind a summary, and the feature only works if users look at each guess before accepting it. Tabs split the set across views, which broke the bulk action. The list won because it kept every drive scannable and individually correctable while still letting one action classify them all. Both halves of that change are rebuilt live in the Garage, from the single-drive gesture this replaced to the bulk review pattern that replaced it.
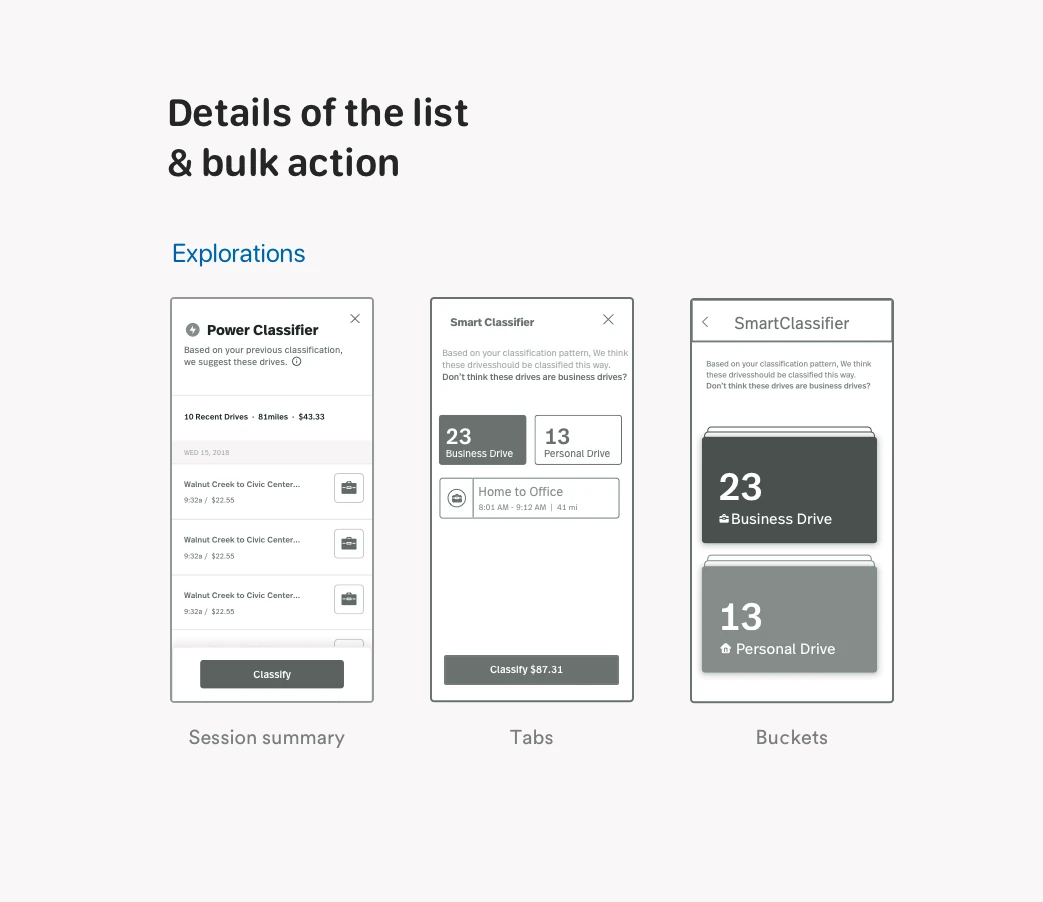
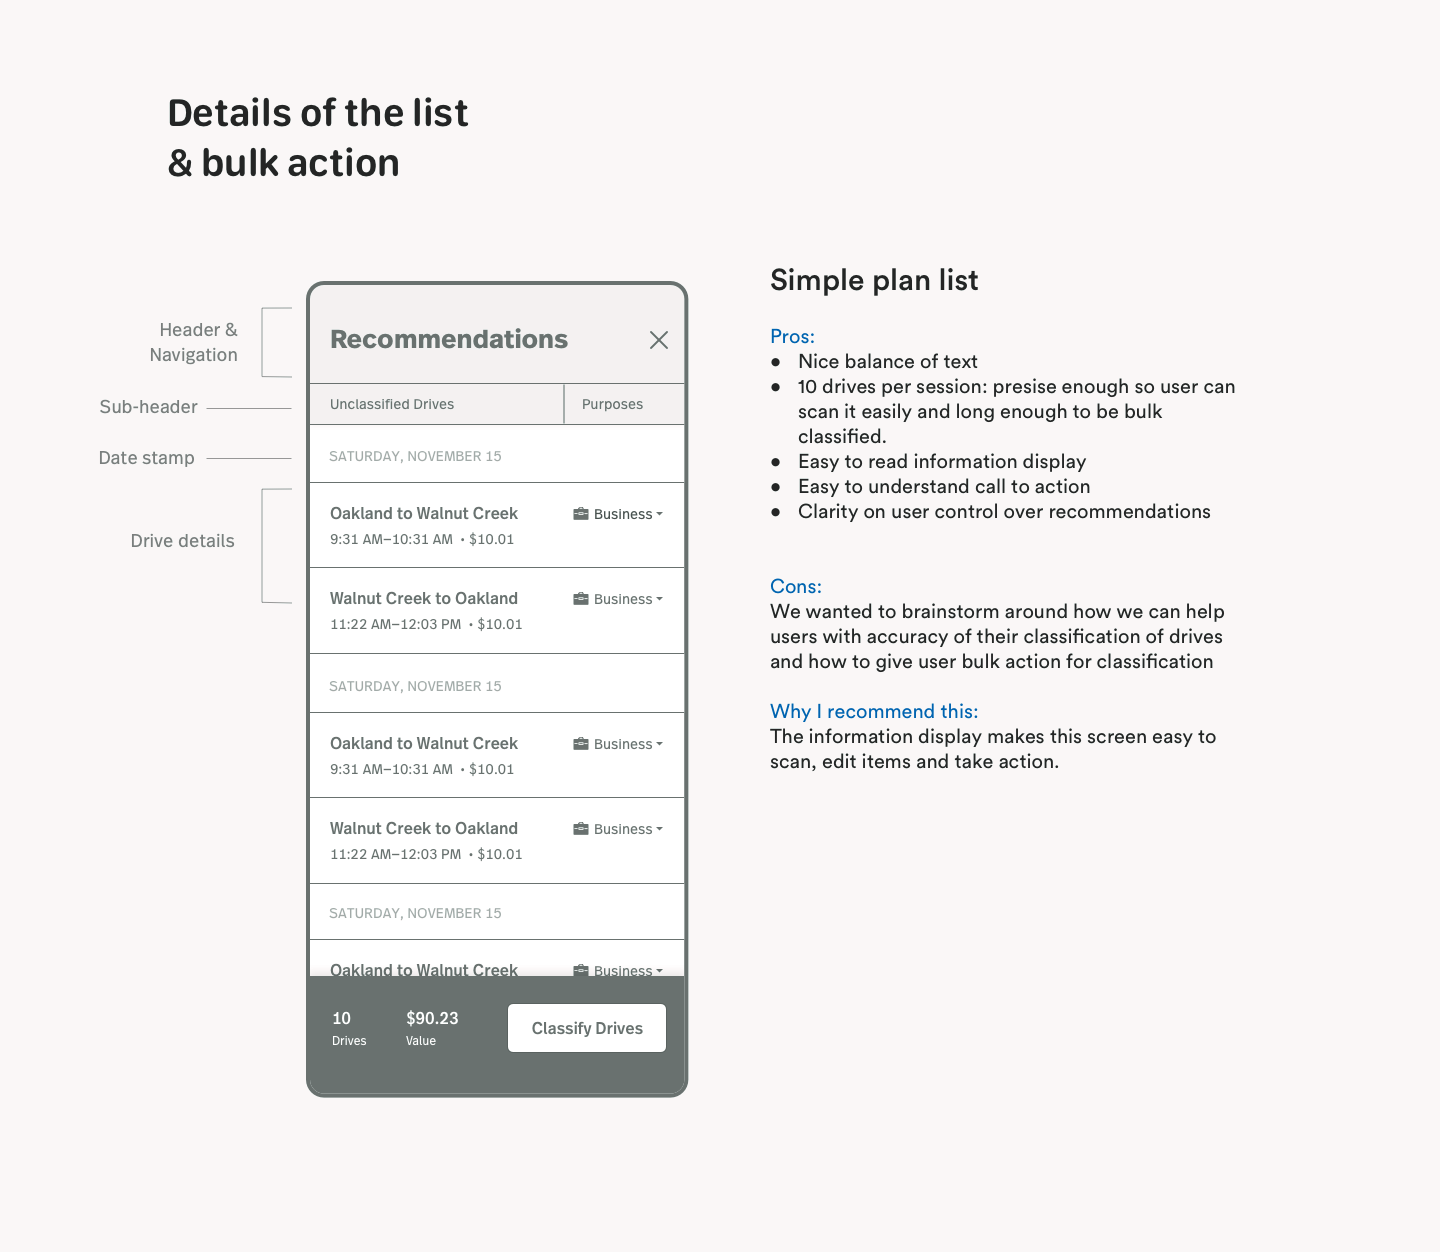
I capped each session at 10 drives to keep the list scannable, so a user with 40 unclassified drives moves through four sessions. I took the friction in exchange for a list that never turned into a wall (see reflection).
A Floating Action Button as the entry point
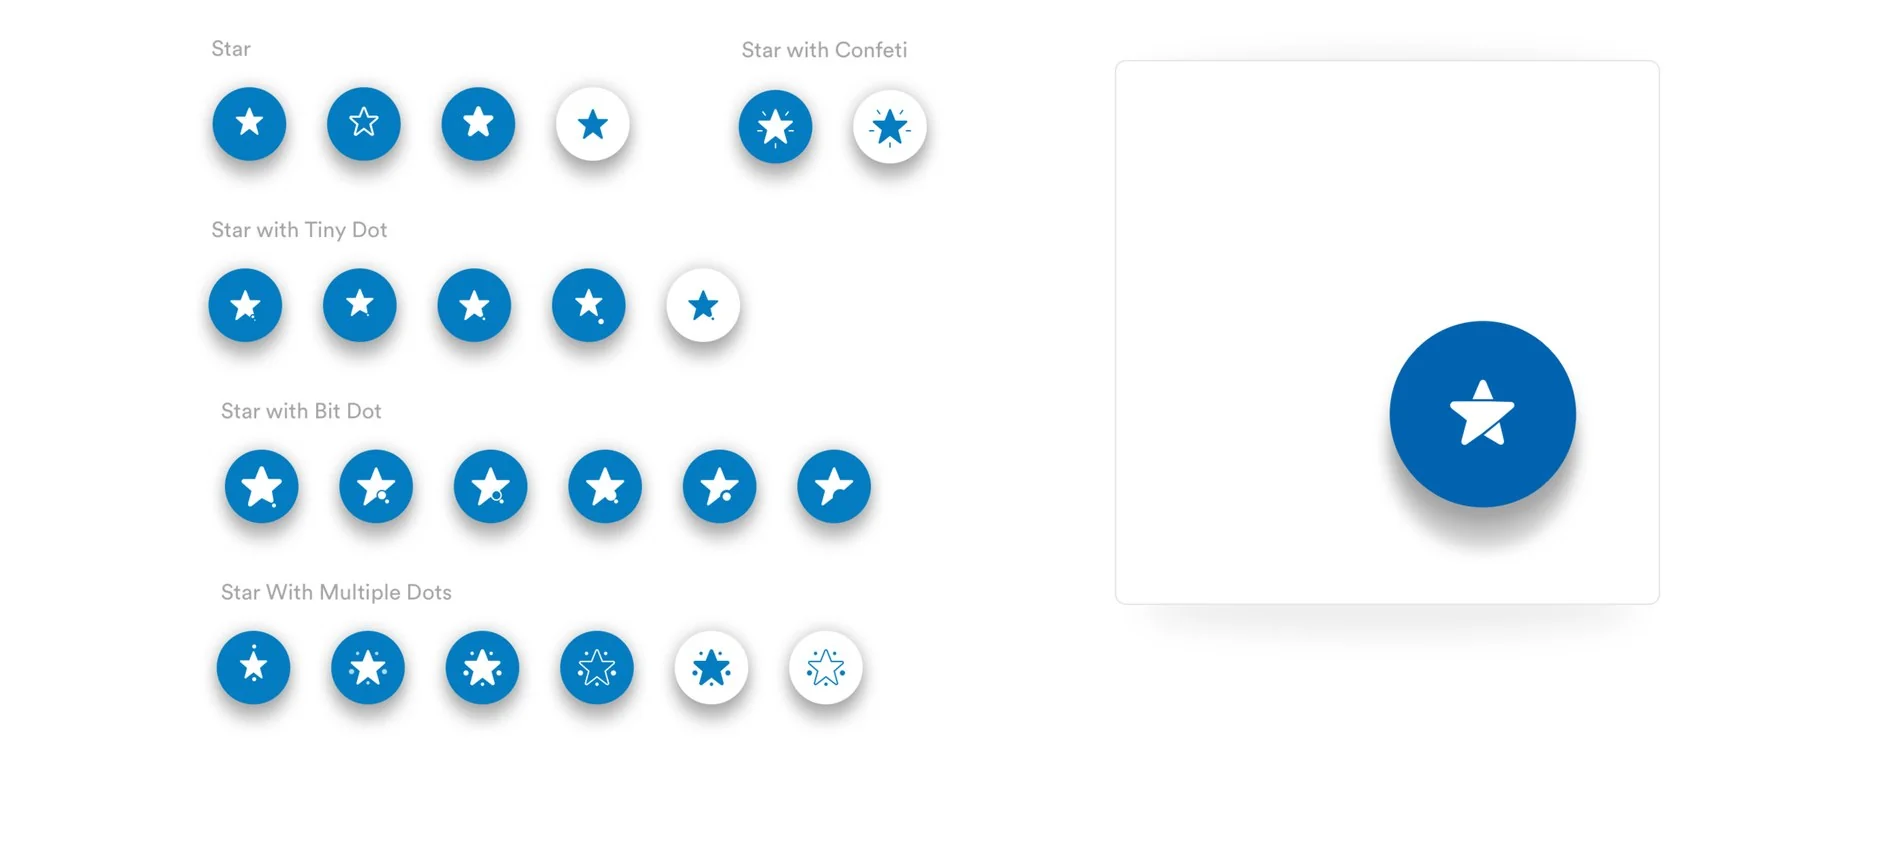
I put the feature behind a FAB instead of threading it into the existing feed. A persistent, consistent entry point meant users always knew where recommendations lived, kept the interaction linear and easy, and let me introduce an entirely new ML feature without disrupting the classification flow users already knew.
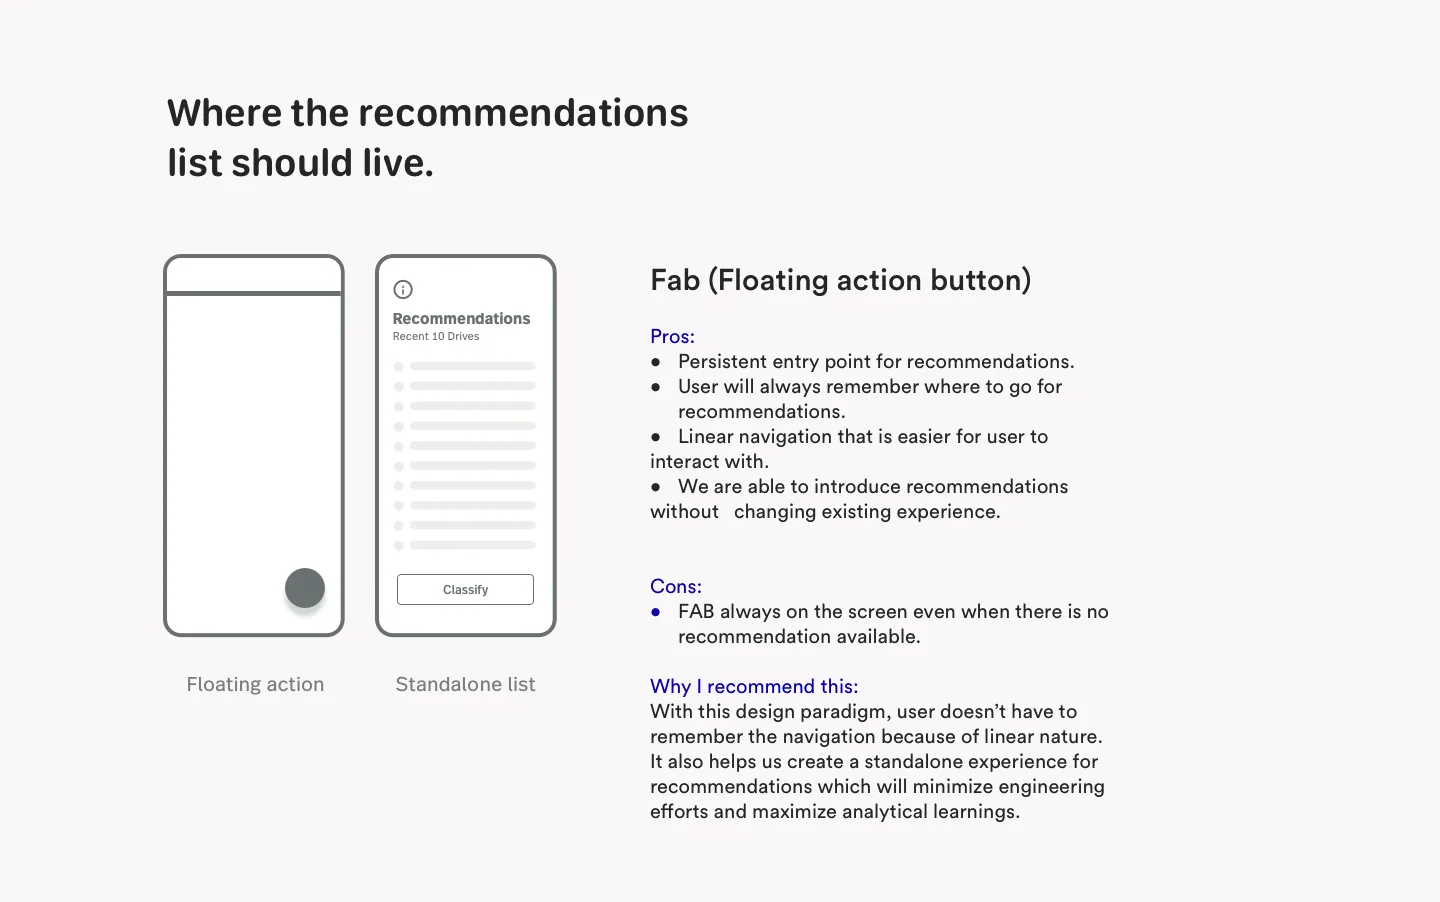
The FAB stays on screen even when there are no recommendations to show. I judged a predictable home users could always find worth more than a perfectly contextual button.
Designing for trust
An ML recommendation is only useful if the user believes it.
The flow was the easier half. The hard part was making a feature that will sometimes be wrong feel worth trusting, without taking control away from the user. Three things did that.
1 Set expectations about the ML itself
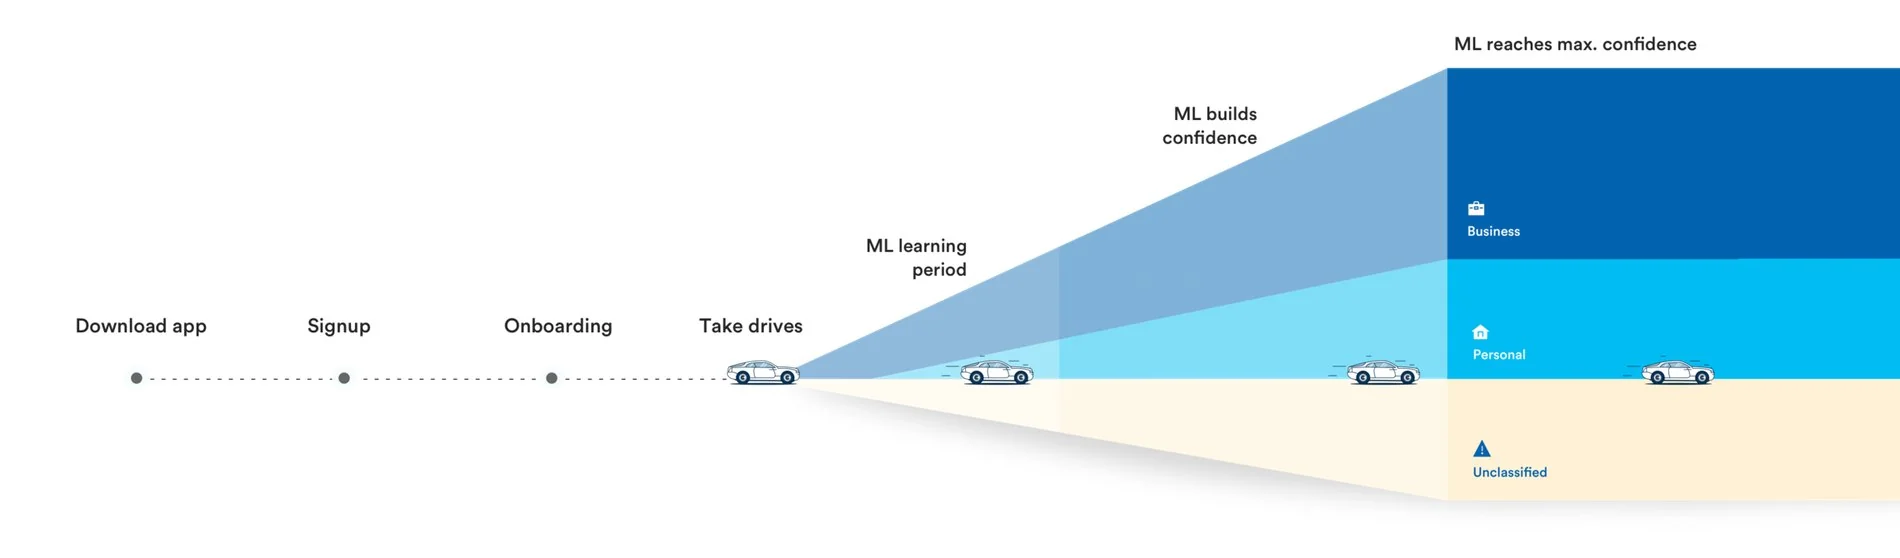
I framed the feature as something that learns. The model starts in a learning period and builds confidence as the user classifies more. That turns an early wrong guess from "this is broken" into "this is still learning," and makes the user's corrections feel like training the system instead of cleaning up after it.
2 Keep the user in control
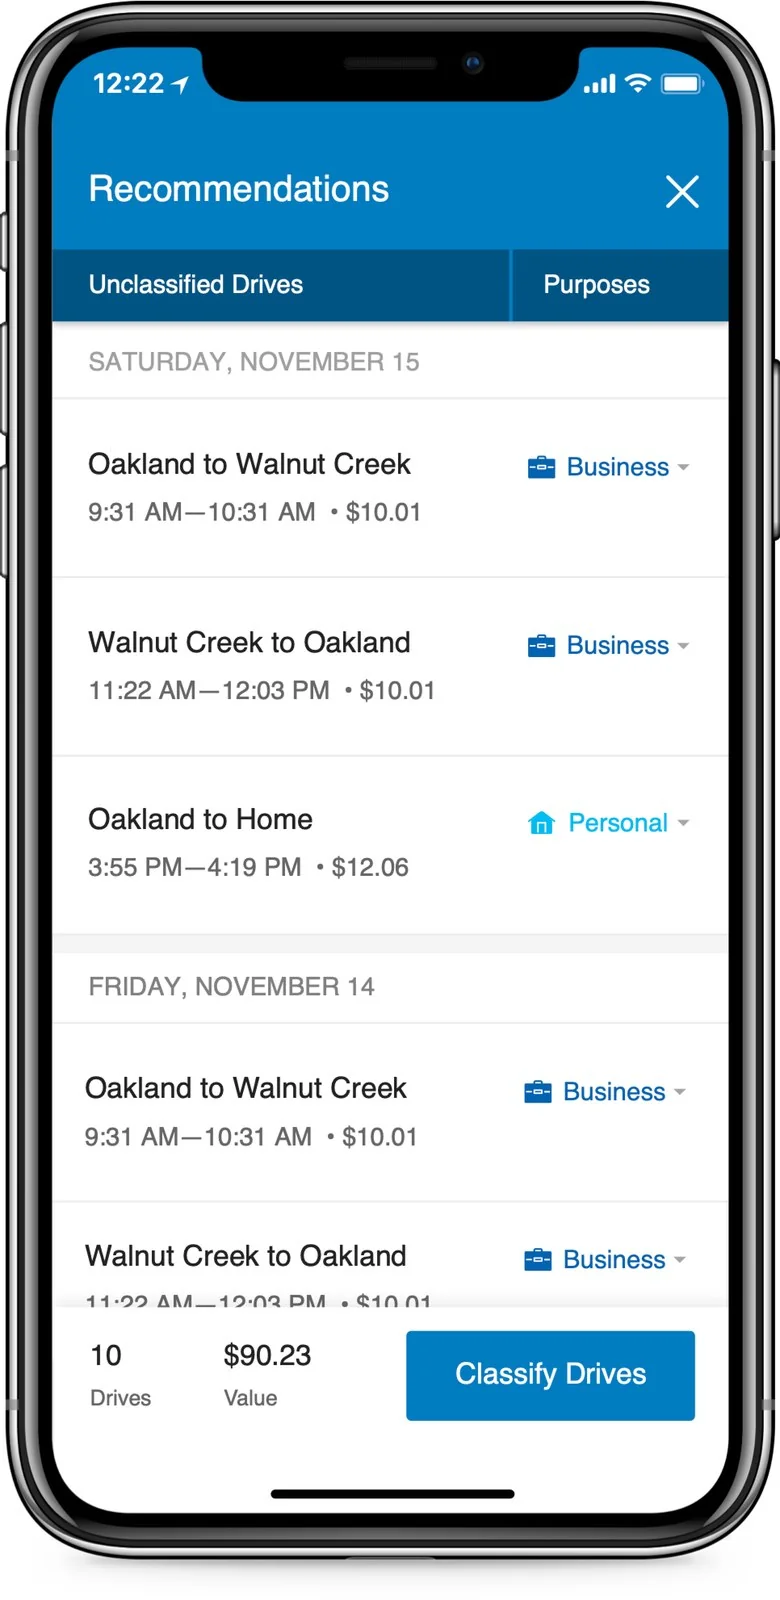
Every recommendation is reviewable and editable before it's applied. The machine suggests. The user decides. They review the suggestions, correct what's off, and commit in bulk.
3 Show the payoff
Working with our UX writer, I tied the language to payoff and progress. "Review, Edit and Classify" sets the task, "10 Drives Classified: that's a $90.23 value" makes the benefit concrete the instant it lands, and a completion state closes the loop.
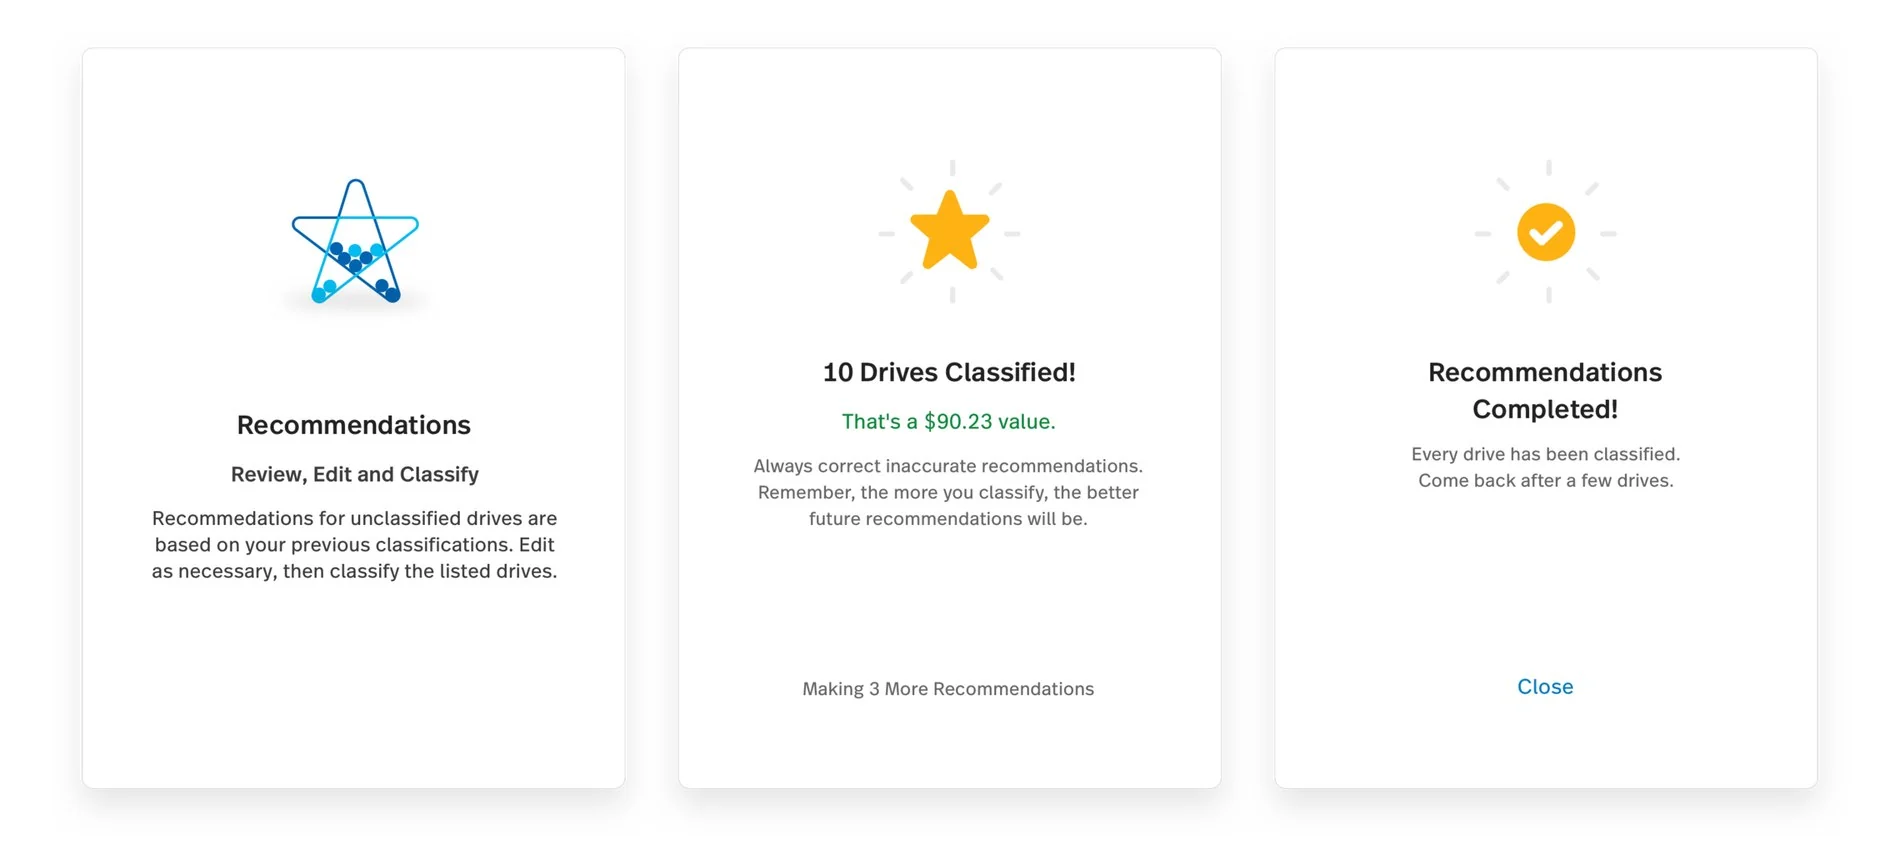
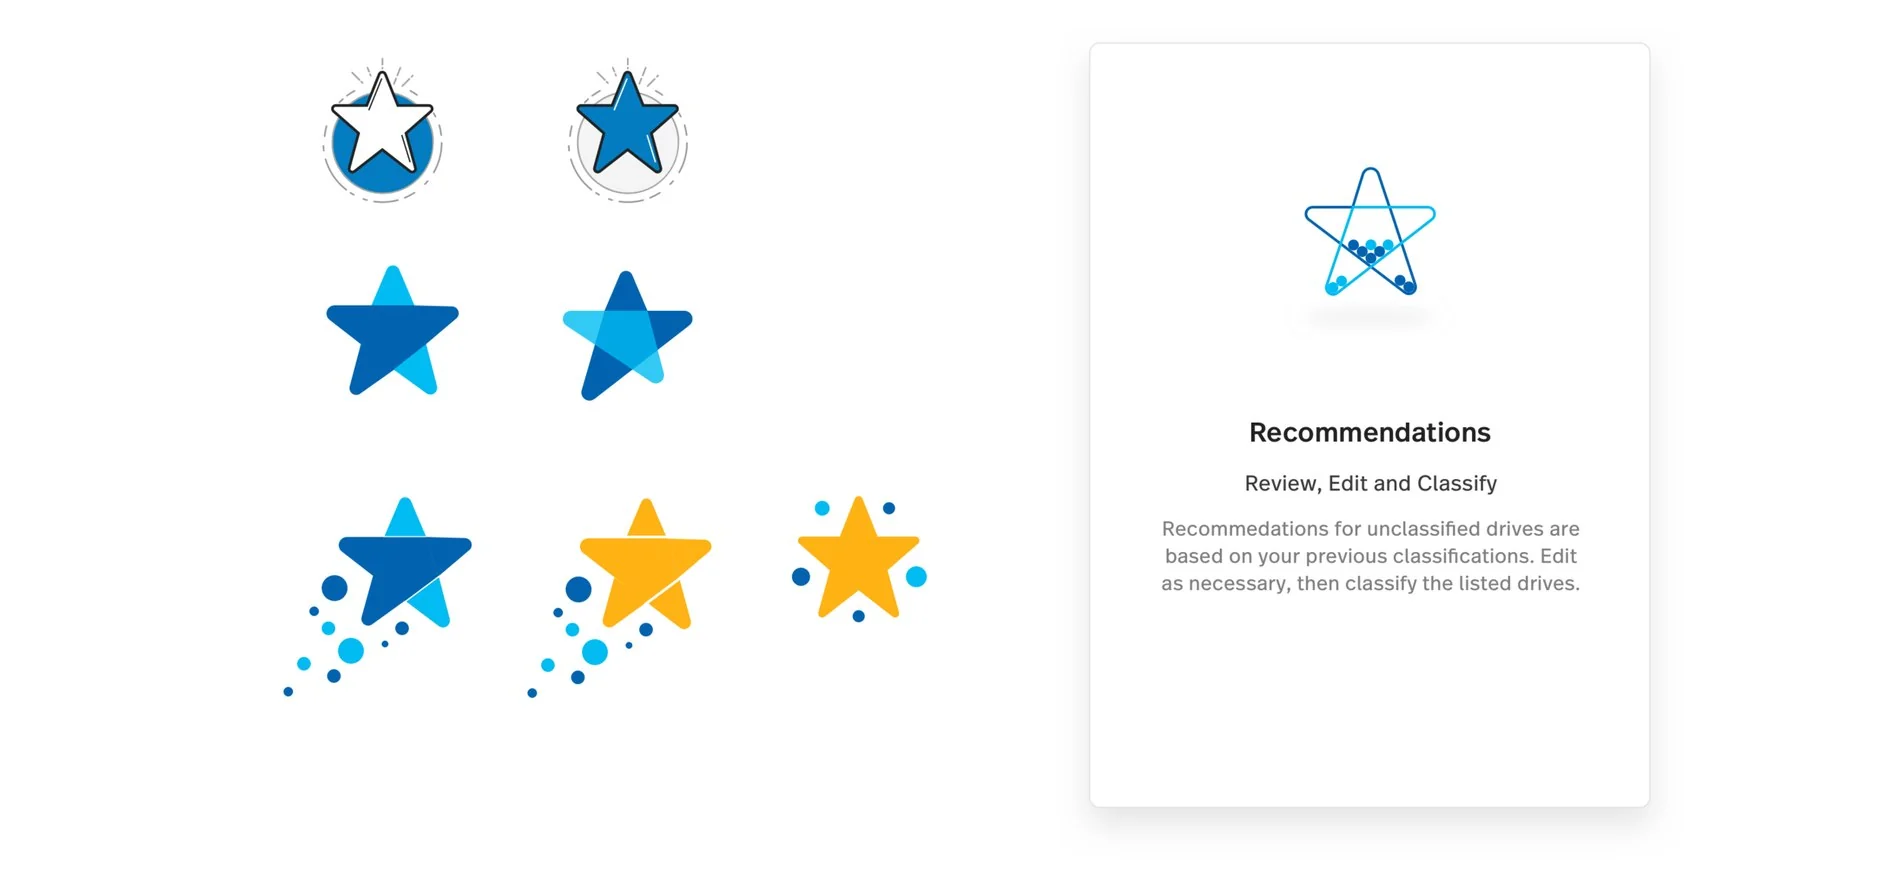
I also reused MileIQ's existing star icon, long used in the app to mark task completion, so a brand new feature felt native. The recommendation mark folds the classified drives into the star.
Final design
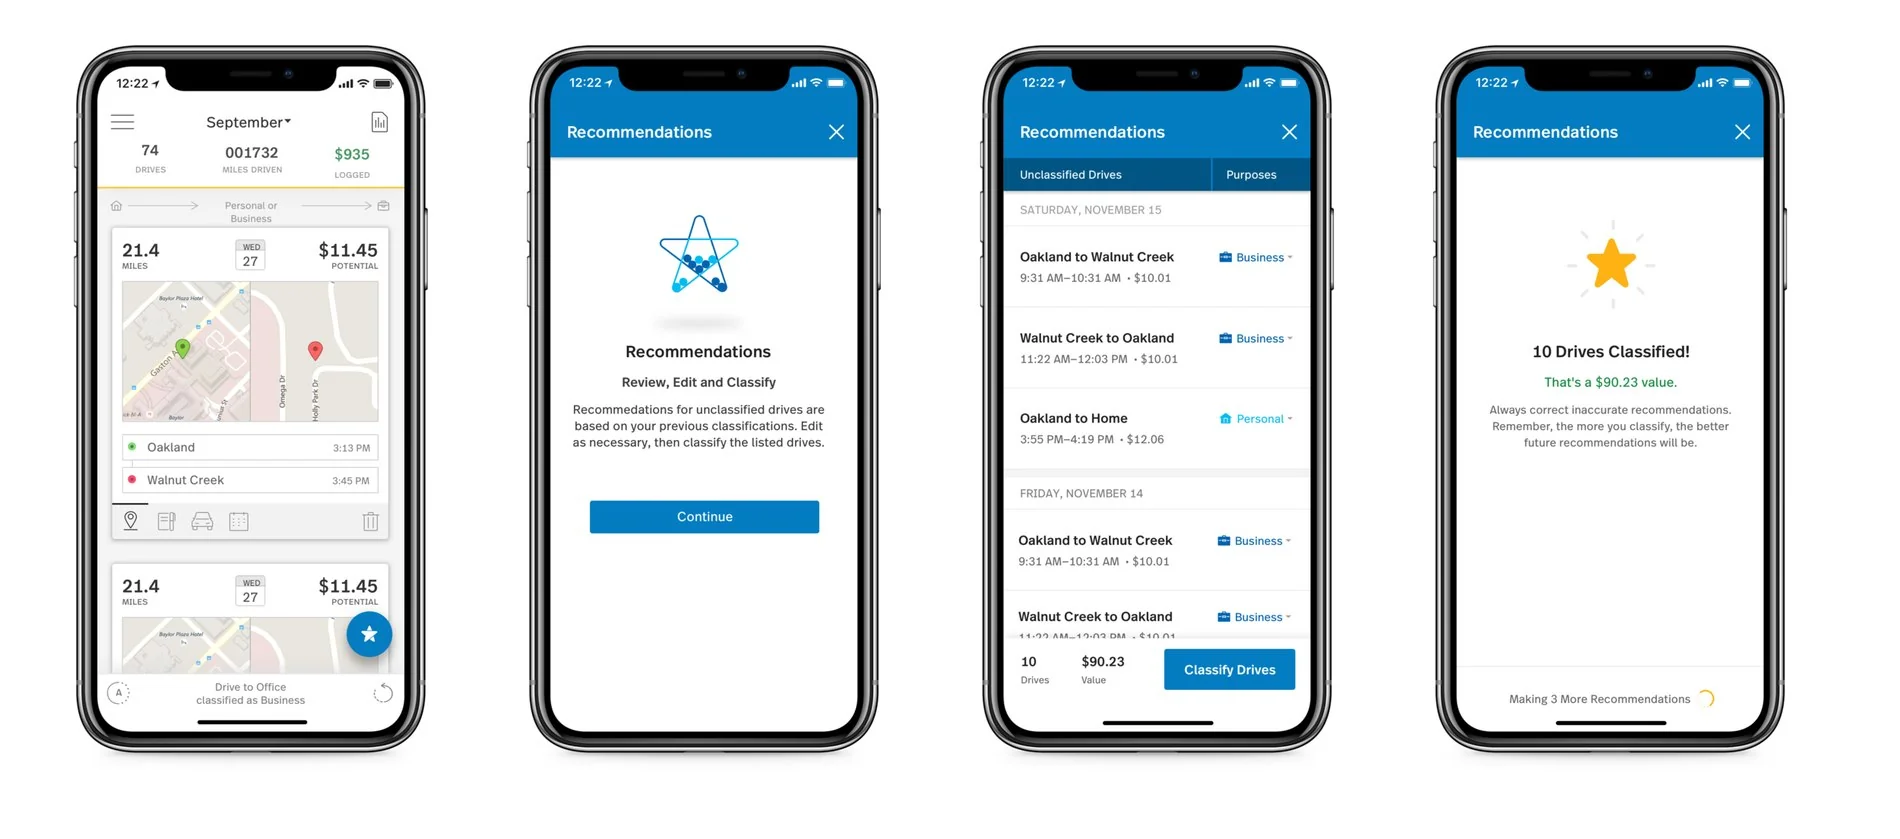
The shipped flow.
From the feed's star entry point, through the intro, the reviewable list, and a completion state that reports the value just unlocked.
Outcome
The feature moved the classification rate, the share of logged drives users classify, by roughly 10–20 percentage points. Users also reported more confidence in their classifications, which answered the accuracy anxiety the research had surfaced.
I left before the numbers fully settled, so the range is approximate. The direction wasn't in doubt.
Why it mattered
Classification is the function the whole product depends on, and every unclassified drive is value the user paid for and didn't capture. Lifting the rate protects retention and the renewal case.
Microsoft Patent Award
Microsoft filed a patent on the ML model behind the feature, and the team, including me as its product designer, received the Microsoft Patent Award. The patent covers the model. I designed everything around it, from how users review and correct to the bulk classification flow.
What I'd do differently
Capping sessions at 10 drives was the right call for launch but the first thing I'd revisit. For users with large backlogs it turns one decision into several sessions. I'd test a progressively loading list or an adjustable batch size, keeping the list scannable without forcing repetition.